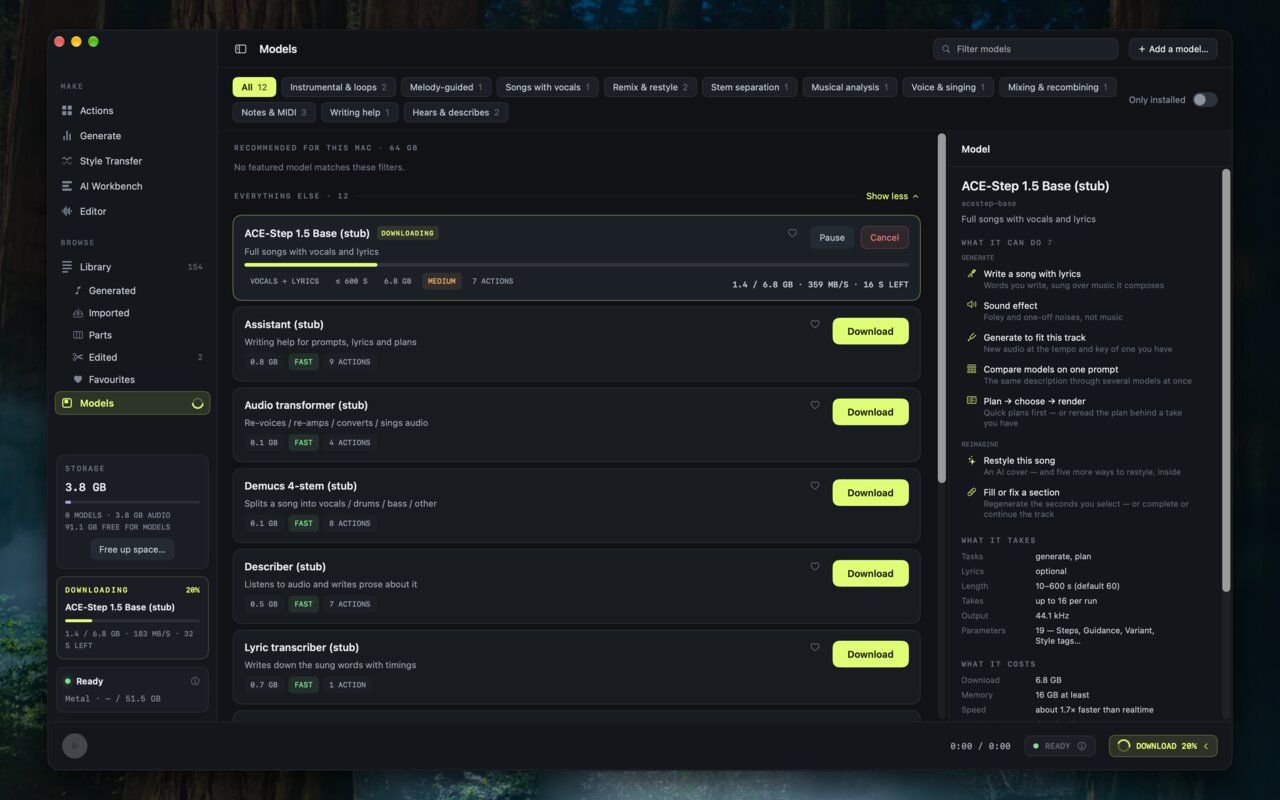
136 Models, 39 Families
Models that write songs from a description and lyrics, split recordings into stems, listen and write down what they hear, and the tooling to chain them together.
Run open music models on your Mac. Generate, separate, transcribe and restyle, with nothing sent to the cloud.
Models that write songs from a description and lyrics, split recordings into stems, listen and write down what they hear, and the tooling to chain them together.
Models download once from Hugging Face and run on the Mac’s own GPU and unified memory. No accounts, no API keys, no cloud.
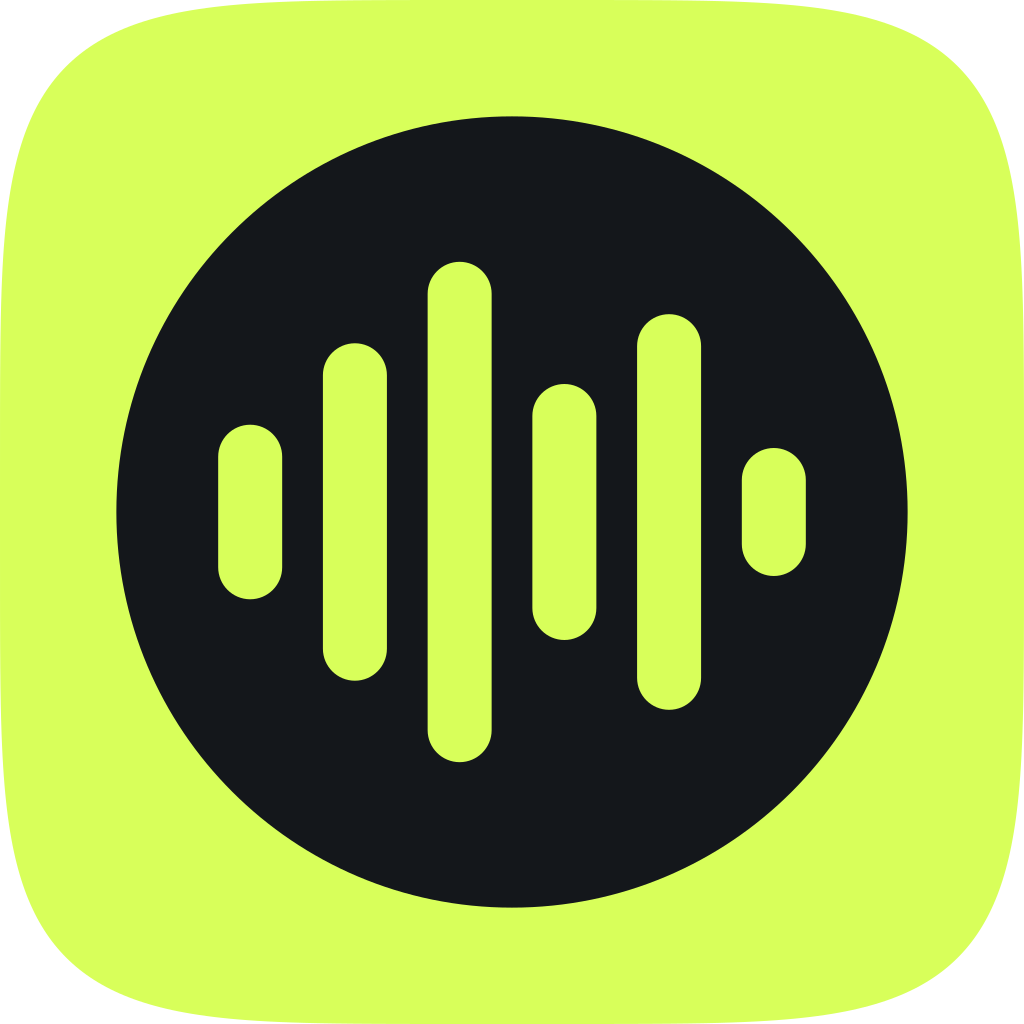
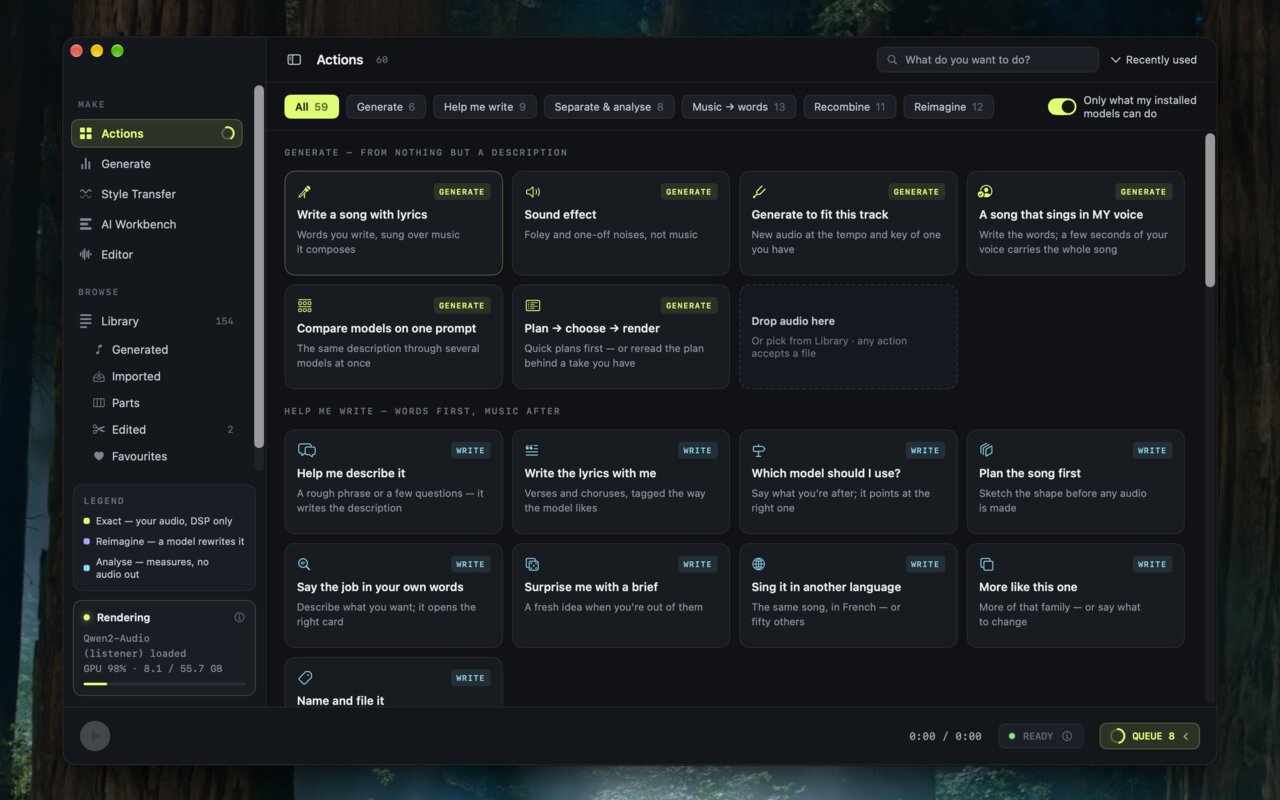
Sixty recipes on six shelves. Each card says what it needs, what it makes, and whether it’s Exact (your audio, DSP only), Reimagine (a model rewrites it), Analyse, Generate or Write.
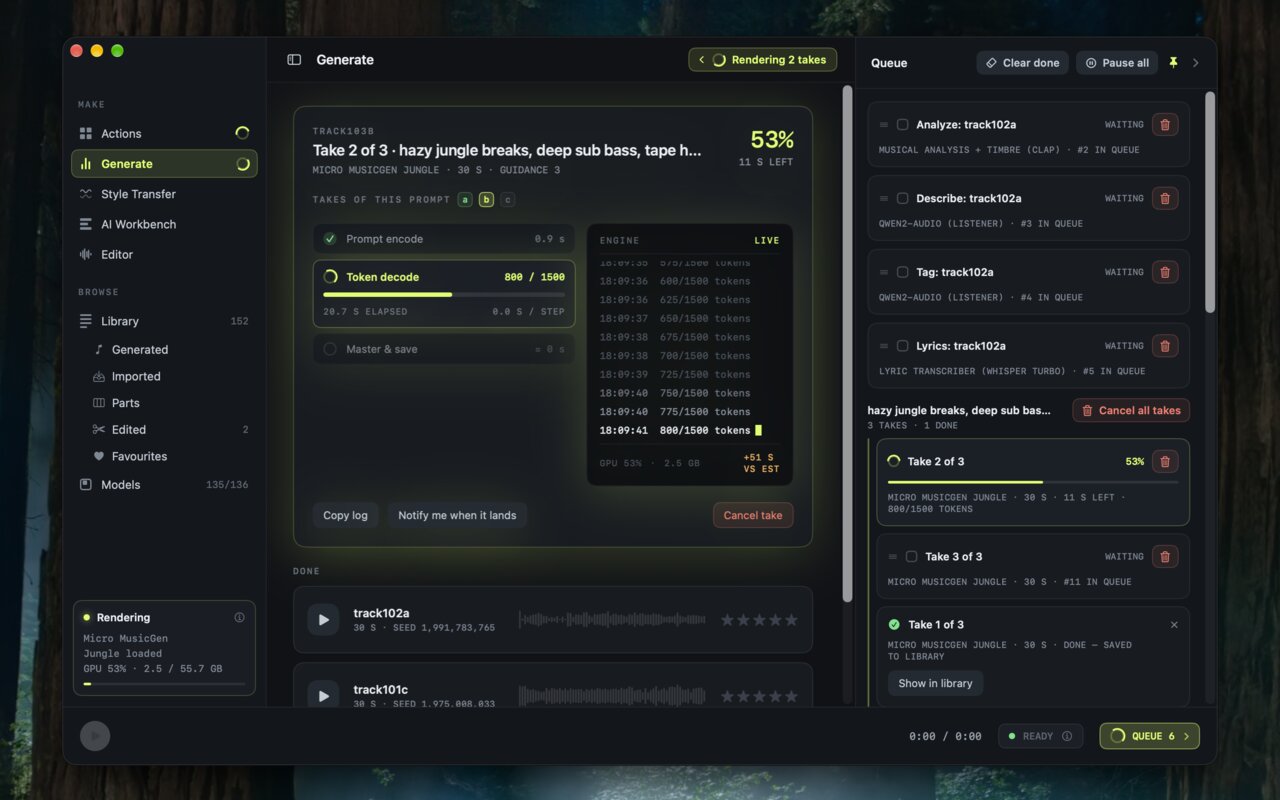
One prompt, one length, one button, or every parameter a model declares. Transform existing audio eleven ways: keep the melody, sound like a reference, extend it, replace a section.
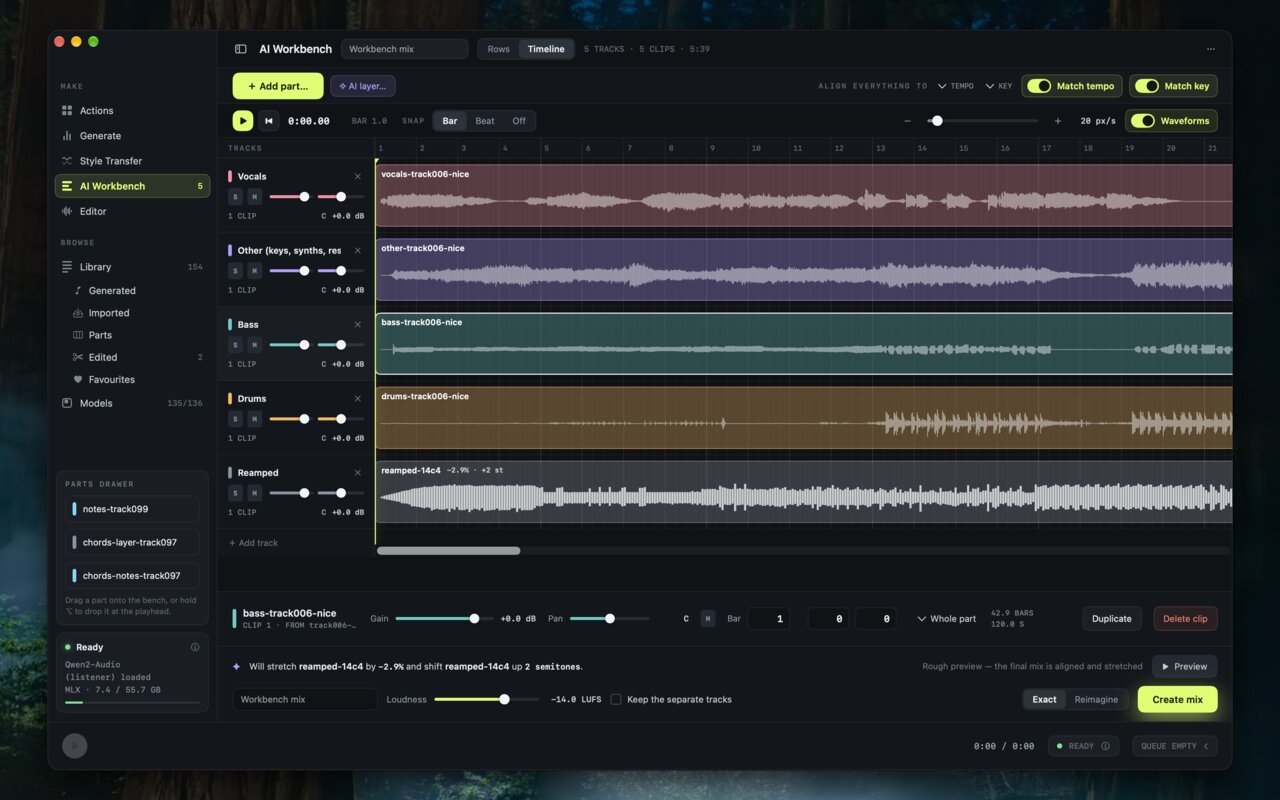
A multi-clip timeline. Drag parts from different songs onto lanes, then render an exact mixdown with tempo and key matching, or let a model play the arrangement.
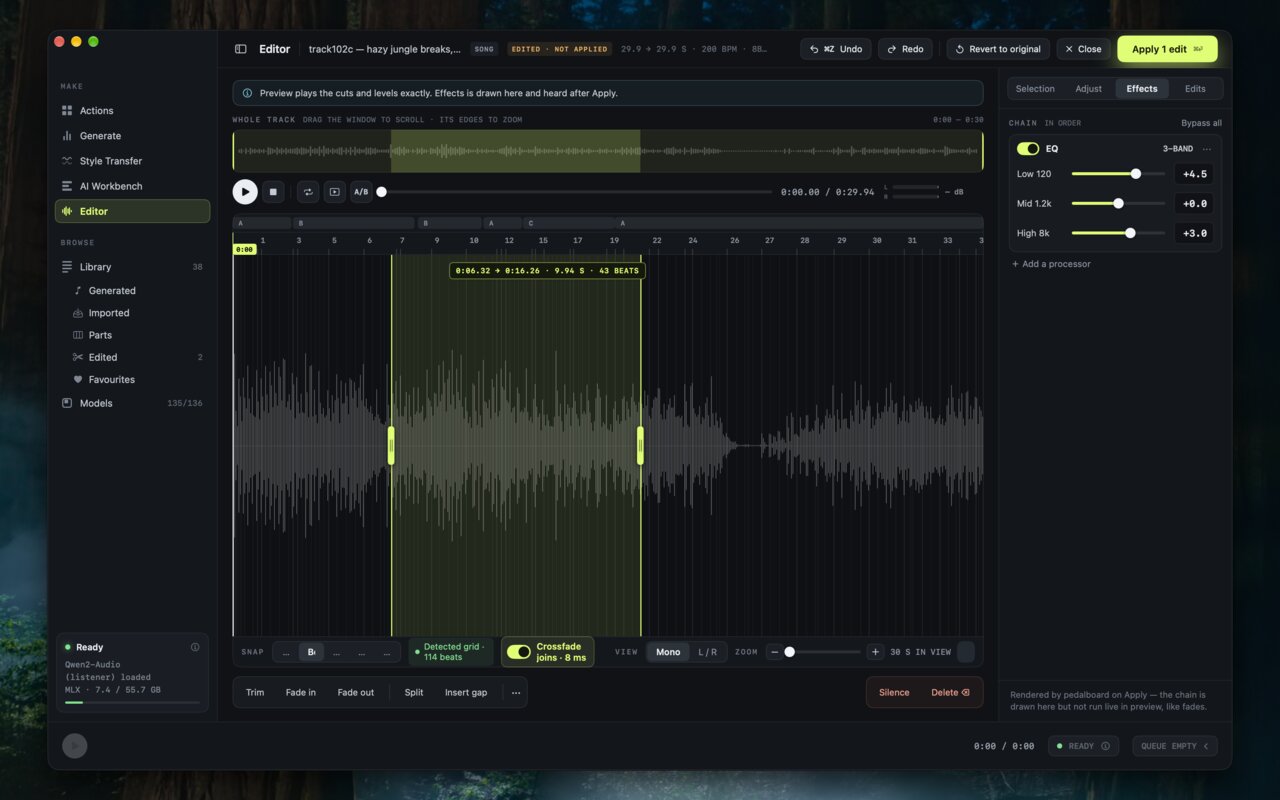
Non-destructive trim, split, fades, normalise, EQ, compression and convolution reverb. Anything transcribed to notes opens as an engraved score you can hear and export.
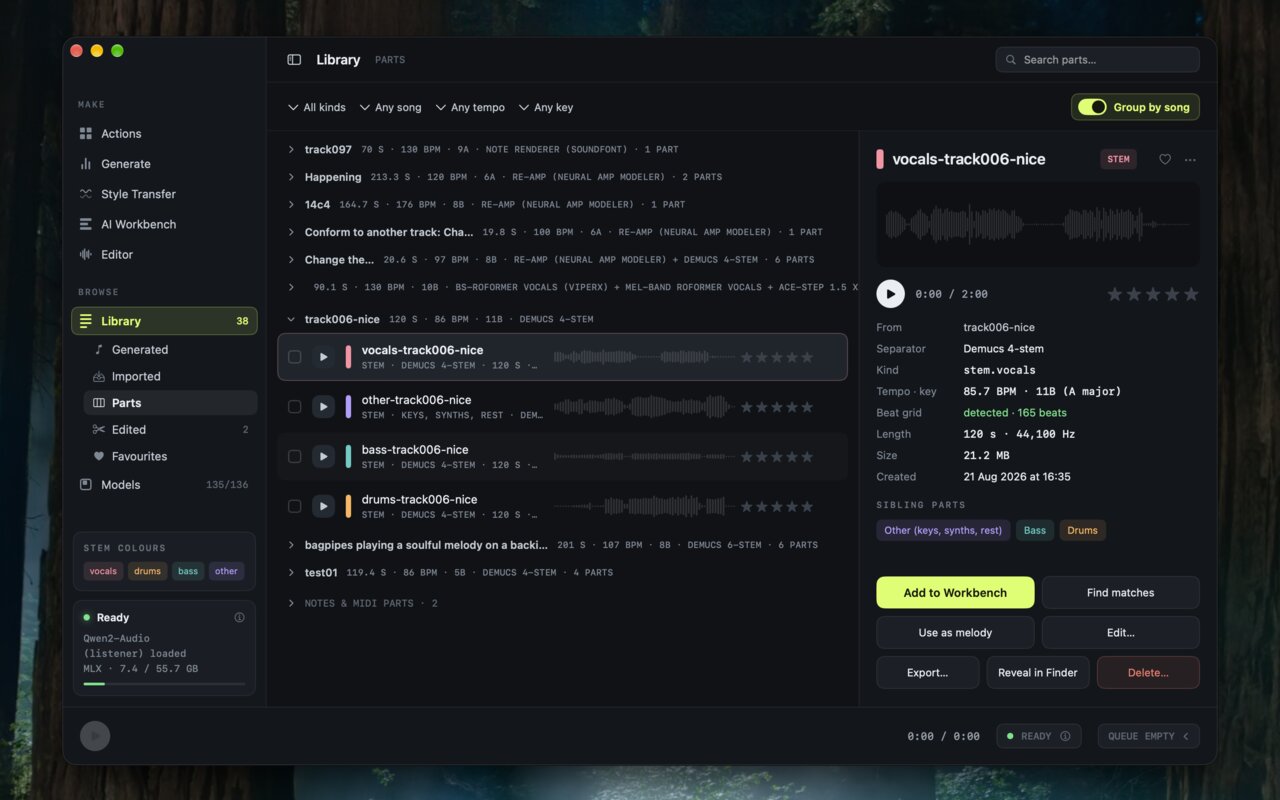
Every song, stem, MIDI file and render, kept with the model, seed and parameters that made it. Full-text search, ratings, tags, notes and A/B compare.
Describe a track, transcribe its lyrics, tag genre and mood, map its sections, read its chords. A small local language model drafts descriptions and lyrics for you.
Once a model is downloaded, nothing leaves the machine.
Models come from Hugging Face and their publishers over ordinary HTTPS; a few gated ones take a Hugging Face token that’s kept in the Keychain. The app and its engine talk over localhost only. No accounts, no analytics, no servers of ours.